# Map CSV columns to the fields your app expects
Handle CSV files with different headers using destination fields, aliases, and an editable column mapping workflow.
Canonical HTML: https://www.csvjetty.com/guides/csv-column-mapping
## Why CSV headers need mapping
One customer exports Full Name. Another exports contact_name. Your application expects name. Mapping connects each source column to a stable destination field so your save code can work with one record shape.
| Uploaded header | Destination key |
| --- | --- |
| Full Name | name |
| Email | email |
| Company | company |
Field labels explain the destination to users. Field names define the keys your application receives.
## Configure destination fields
Create an importer in the CSVJetty dashboard, select callback delivery, and copy its importer key. Replace YOUR_IMPORTER_KEY in the examples with that key.
You can save fields in the dashboard or pass them through the columns prop. This example uses code so the field names, types, and aliases are visible together. Passing columns replaces the saved dashboard fields for this import session.
```bash
npm install csvjetty
```
```jsx
import CSVJetty from "csvjetty";
const columns = [
{
"name": "name",
"label": "Full name",
"type": "text",
"required": true,
"aliases": [
"Full Name",
"contact_name"
]
},
{
"name": "email",
"label": "Email address",
"type": "email",
"required": true
},
{
"name": "company",
"label": "Company",
"type": "text",
"required": false
}
];
export default function ContactImport() {
return (
console.log(rows)}
>
Import contacts
);
}
```
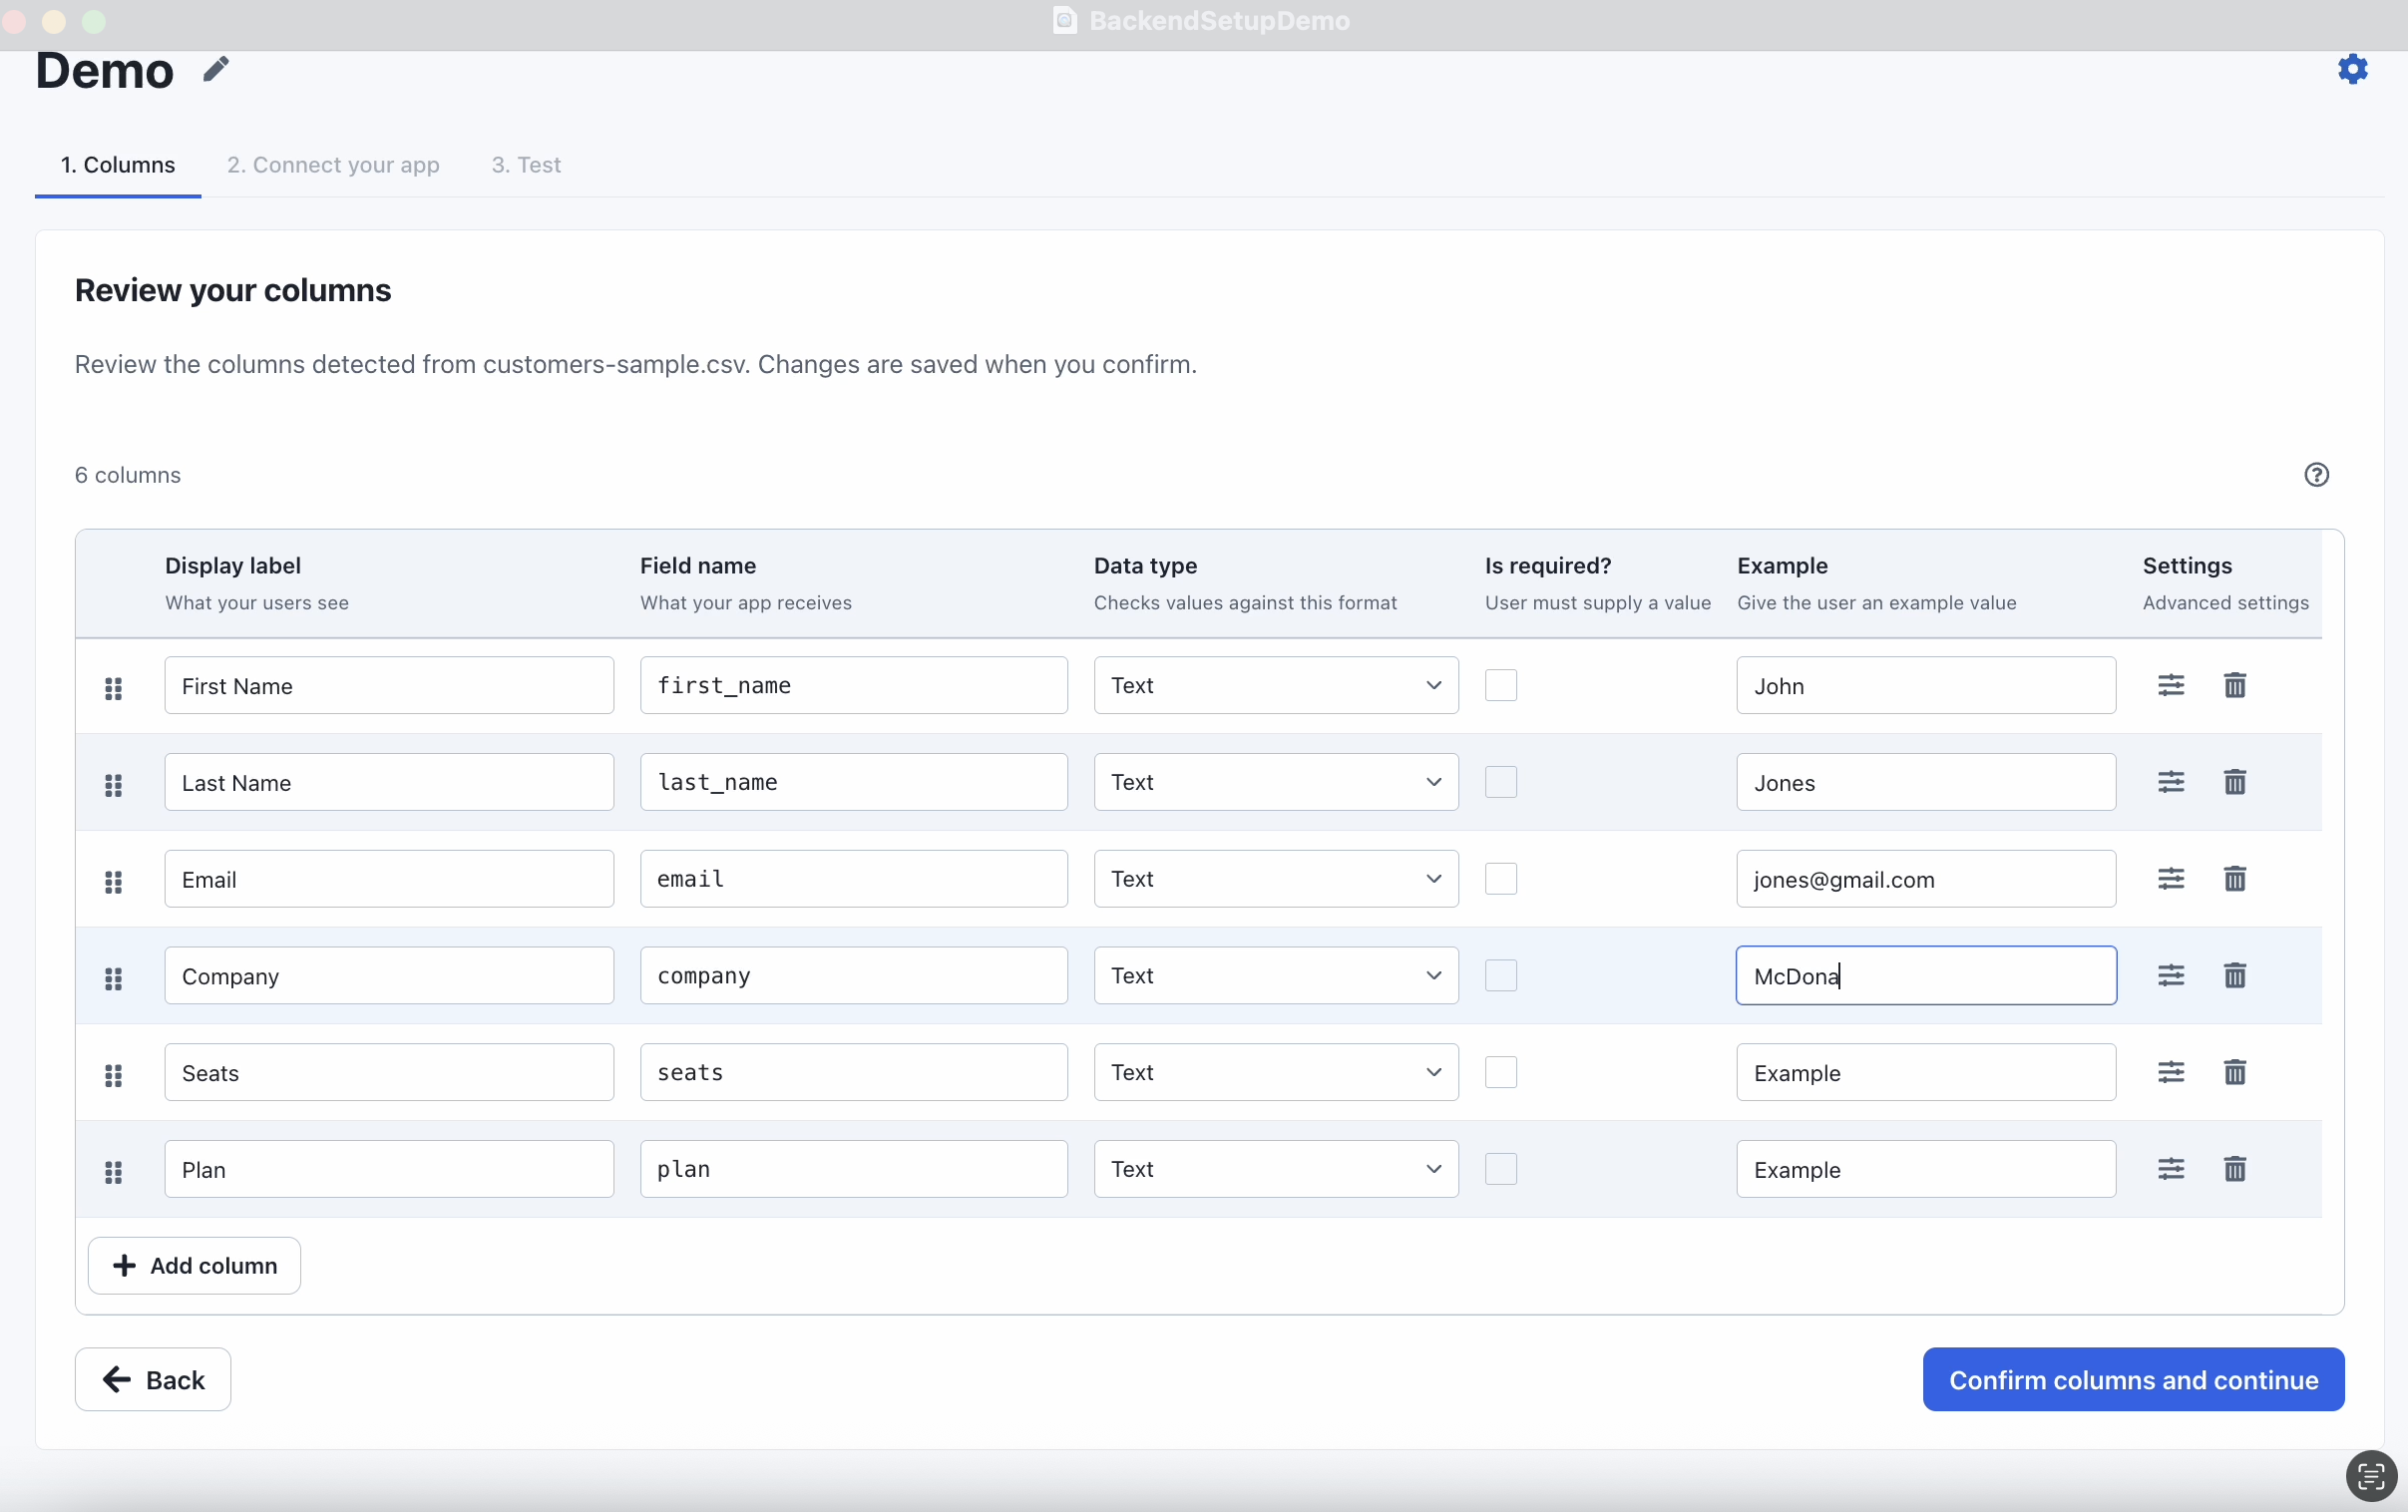
Dashboard configuration example. The screenshot uses a different schema from the contact examples below; configure the fields specified in each guide.
## Use aliases for familiar headers
The name field includes Full Name and contact_name as aliases. Aliases help automatic matching when users upload familiar variations. Users can review and change the selected matches before completing the import.
Keep aliases specific to one destination. A vague alias such as ID can be ambiguous when an importer expects both a customer ID and an order ID.
## Test mapping with a real CSV
[Download contacts.csv](https://www.csvjetty.com/samples/contacts.csv)
```csv
Full Name,Email,Company
Ada Lovelace,ada@example.com,Analytical Engines
Grace Hopper,grace@example.com,Compiler Works
Katherine Johnson,katherine@example.com,Orbital Systems
```
Upload the sample, review each source-to-destination match, and complete the import. Check the browser console for delivered records. Rename Full Name to contact_name and upload again to test the configured alias.
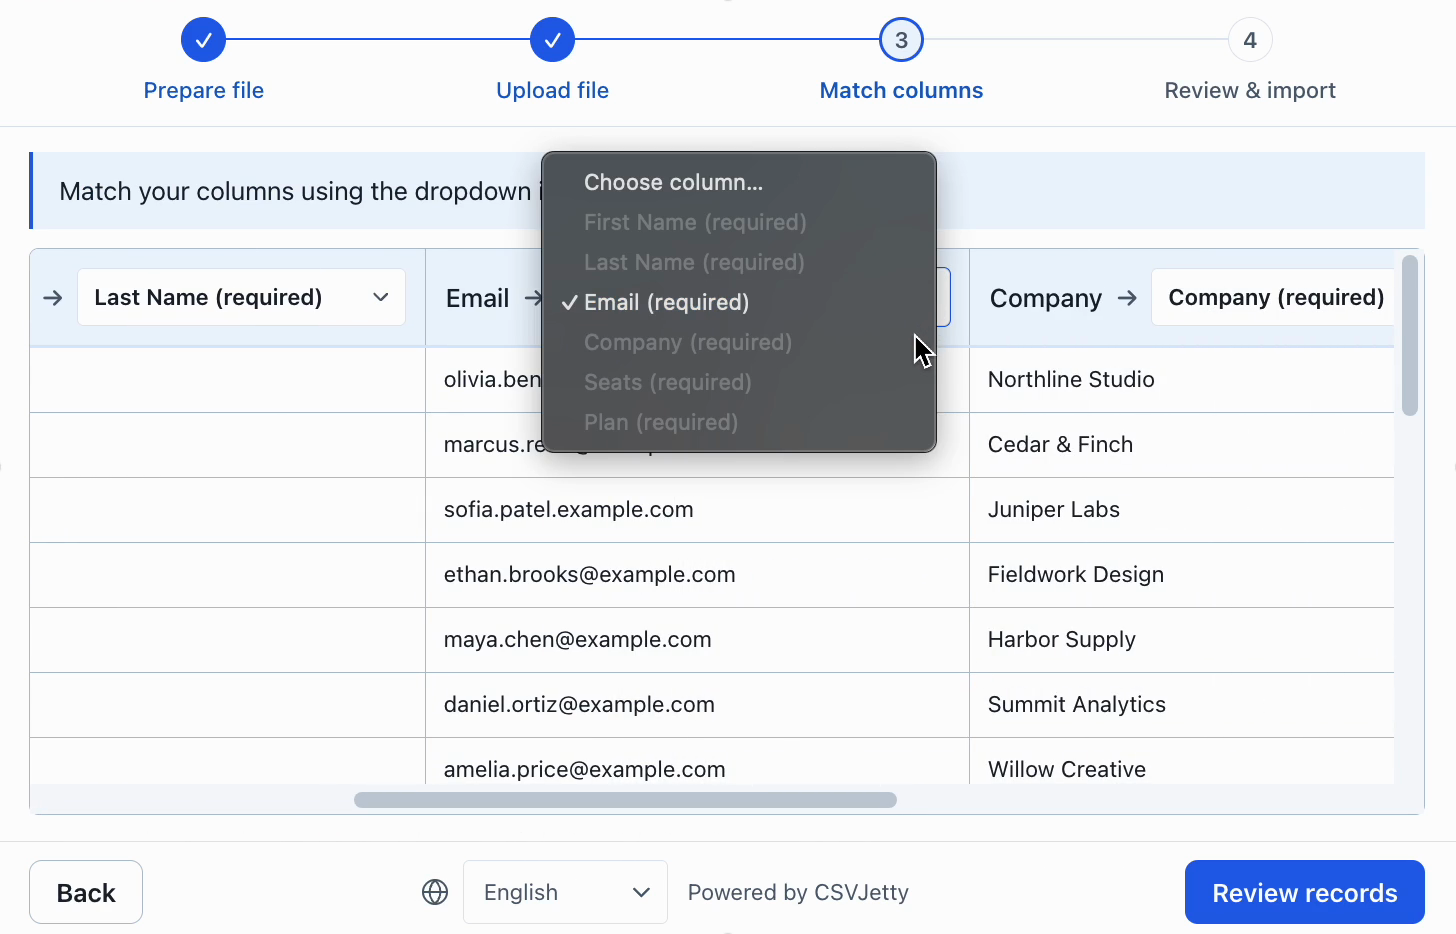
Customers review the source records and adjust destination fields in each column header. The screenshot uses the demo schema.
## Consume stable output keys
```json
{
"name": "Ada Lovelace",
"email": "ada@example.com",
"company": "Analytical Engines"
}
```
Use these destination keys in your application. The callback payload also includes uploadedFileHeaders and matchedColumnsMap when you need source context for an import log.
[Read the import payload reference](https://www.csvjetty.com/docs/reference/import-payload)
## Handle missing and extra columns
A required field needs both a column match and a nonempty value. An optional field lets users import files that do not contain that information. Decide which fields your application truly needs before marking them required.
If unmatched-column delivery is enabled, extra values can arrive in each record under _unmatched. Check your importer settings before relying on those values.
[Read column configuration options](https://www.csvjetty.com/docs/columns)
## Use a different schema for each import session
The columns prop replaces dashboard fields for the session. Supply the whole destination schema, not only the changed field. Build that schema from the application’s known entity configuration, rather than treating arbitrary uploaded headers as trusted database column names.
```jsx
const schemas = {
contacts: [
{ name: "name", label: "Full name", type: "text", required: true, aliases: ["Contact Name"] },
{ name: "email", label: "Email", type: "email", required: true, aliases: ["Work Email"] },
],
products: [
{ name: "sku", label: "SKU", type: "text", required: true, aliases: ["Item Code"] },
{ name: "name", label: "Product name", type: "text", required: true },
],
};
// entity is an application-owned choice. Remount when it changes.
Import CSV
;
```
saveForSelectedEntity must be your authenticated save handler, not a database client exposed to the browser. Close the current import before switching entity types; do not change its expected schema mid-session.

Configure destination fields and their types. This recording frame uses the demo schema; use the schema specified in this guide.
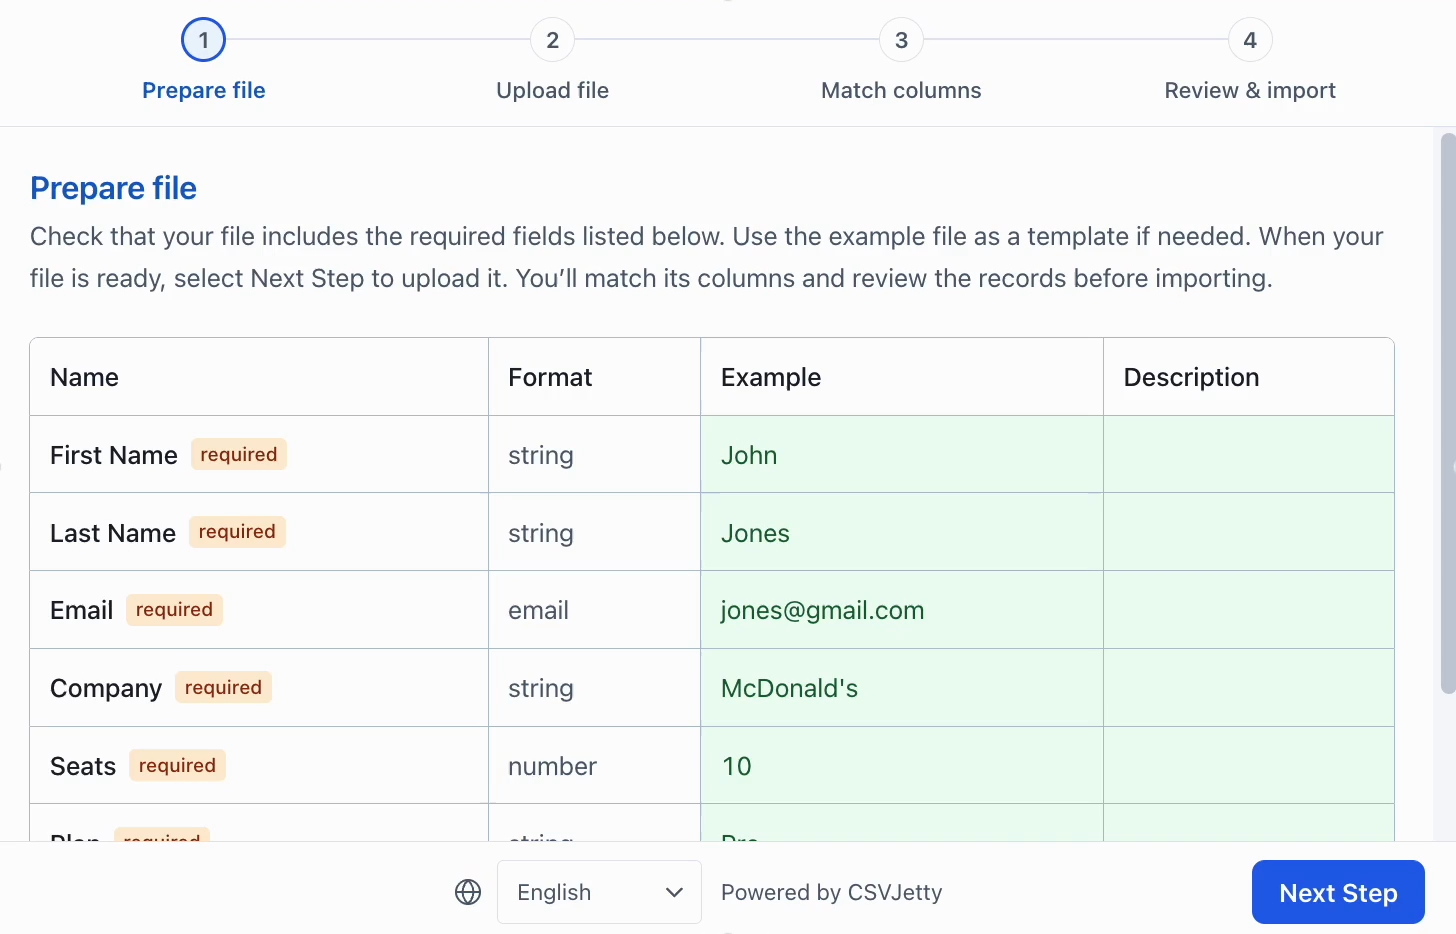
The preparation step explains the expected fields before upload. The fields shown belong to the demo importer.
[Complete contact importer](https://www.csvjetty.com/guides/import-contacts-csv)
[Complete catalog importer](https://www.csvjetty.com/guides/import-product-catalog-csv)